I will no longer upload to NEW
Posted by edward 2 days ago
Comments
Comment by monsieurbanana 2 days ago
They also have a reward system that punishes people for ignoring the llm review (by pushing their submission lower in the queue).
Comment by cromka 2 days ago
This here might hit the nail on the head exactly in terms of what the biggest FOSSes gripe with LLMs with might be: not the fact people use it but rather how it hinders the communication.
If you use it to help the write code, but you explain things in your own words or, at very least, redact and trim LLMs output, it's fine.
If you, however, just drop a wall of text at someone and expect they act on its b/s, this is lazy to the point it borders with microagression.
You wouldn't expect a distinguished professor explain basic maths to a student, and we shouldn't expect actual developers address Copilot's stupid, unredacted hallucinations or otherwise unrelated remarks.
This works for patches submission, too: you should be outright banned for submitting stuff you didn't bother to double check and properly document.
Comment by unrented7977 1 day ago
Comment by bradknowles 1 day ago
It’s the LLM equivalent of “an eye for an eye just makes everyone blind”.
Comment by Cthulhu_ 1 day ago
Either some consensus emerges or it just deadlocks in place. My money is on the latter. I wish my money was in the companies profiting on it three years ago because that's the only way this will financially benefit people.
Comment by kyorochan 1 day ago
Comment by pluc 2 days ago
Comment by phoghed 2 days ago
Comment by lifeisloving 2 days ago
Comment by bombcar 1 day ago
Once you're drinking from the firehose you realize just how many idiots (well meaning or not) are out there, and how empowered they are now.
Comment by excannuk 2 days ago
Comment by close04 2 days ago
Lazy or incompetent colleagues always forced people around them to overcompensate and correct. AI increased their firepower and blast radius.
Comment by bombcar 1 day ago
The end-game for Anthropic is each PR to be 100k+ tokens but nobody cares because they burn 100k+ tokens reviewing and responding.
Comment by Cthulhu_ 1 day ago
We'll see the tools get adjusted over time to use more and more tokens, or at the very least they get optimized to use every paying customer's tokens for whatever period so that they are on the one side thinking they're getting their money's worth, or on the other that they should upgrade to a higher tier plan. Because the companies are investing trillions into thousands of datacenters and if they sit unused it'd have been a waste of money.
(the datacenters won't go unused I'm sure; any unused capacity will end up on a spot market, with cryptocurrency generation as a constant baseline. I'm pretty confident that crypto will make another small resurgence after the AI / datacenter investment bubble pops. This is a random internet comment, not financial advice)
Comment by ivalice 22 hours ago
Comment by gspr 2 days ago
This is what I fear will push its way into every part of society soon, too.
"We're not forcing you to do your banking through our AI interface instead of a normal one, you're free to opt out, but multiple functions will be missing and we'll charge you a monthly fee."
"You don't have to have an LLM grade your exam, but beware that the human grader will be overworked and grumpy for the extra task."
Comment by drdexebtjl 2 days ago
If you’ve applied to jobs recently, you must have seen the companies that transcribe and summarize interviews using AI (and probably share data across their clients in an indirect, technically legal way).
You can opt out, of course, but do you really want to be the one candidate for which the interviewer needs to take notes manually? And they just spent a lot of money on this hiring AI tool, will they hire the one candidate for which they couldn’t use it?
Comment by gspr 2 days ago
This is gonna get so much worse. It's like the smartphone revolution on steroids – and we've seemingly learned nothing! We're in dire straits.
Comment by wccrawford 2 days ago
I'm surprised that your doctors weren't asking, and instead were just assuming.
Comment by jasomill 1 day ago
Comment by gspr 1 day ago
Comment by solyin 2 days ago
That's cute. Yo, people be having full on AI-led interviews! That is to say, there's the human interviewee, and an AI, testing the human. Asking them questions and having a conversation that is definitely recorded.
Comment by drdexebtjl 1 day ago
Comment by monsieurbanana 2 days ago
But to upload to debian new's queue you already need to have pre-approval, it's a different situation from e.g. a public git repository that anyone can push to.
Comment by g-b-r 2 days ago
Why would you use an LLM instead of a fixed message?
Comment by monsieurbanana 2 days ago
Another situation where I would use llms to generate messages is if we've mutually agreed to do that. For example automated review messages at work, if we've agreed that it would be a part of our workflow.
A good rule of thumb might be unsolicited vs solicited llm messages.
Comment by g-b-r 2 days ago
If you mutually agreed of course it's fine
Comment by tetha 2 days ago
For example, mine is a technical writing skill based on the old book "The Art of Scientific Writing": Front load information as much as possible - the first paragraph of a document should be a summary, the first sentence of a paragraph should summarize. Short sentences building on each other. Always show evidence.
Someone else spent quite a while optimizing a standardized PR description template, with a section for intent, expected changes, risk, rollout coordination and such.
That made the slop a lot more tolerable.
Comment by InsidiousWombat 2 days ago
Comment by SOLAR_FIELDS 2 days ago
Comment by account42 2 days ago
Comment by agwa 2 days ago
Comment by thesuitonym 2 days ago
Comment by solyin 2 days ago
Comment by thesuitonym 17 hours ago
Comment by bayindirh 2 days ago
While I'm perfectly on the same page with the critics of the LLM generated summaries, I'm a bit torn on the issue.
For anyone not familiar with Debian ecosystem, there's a helper tool called Lintian. Lintian does all kinds of checks from package formatting, licenses to dependency management (which can detect both unnecessary yet included and necessary but missing dependencies via static analysis of your tool if necessary).
It's expected that your package to be "Lintian clean" to be able to included in Debian with minimum friction and wait. Even though it's Lintian clean, your package also checked by teams which are severely understaffed, and composed solely of voluntary people.
NEW queue also receives tremendous influx of packages (which can be considered a torrent, even). Since noon, there are 10 more ITP (intention to package) bugs open in my inbox.
As a result, at one hand, these people need every help they can get because getting new trainees and getting them to learn the intricacies is hard, on the other hand LLM generated text rightfully generate negative reactions from people. However, giving developers an automated check of what looks right and what looks wrong is helpful, in my perspective.
I wonder what people would have said it was a deterministic tool generating these reports and sending people these summaries as a "hey consider this feedback until a human has time to see your package".
This is a hard question and we need to think before impulsive reactions. I even don't have all or any of the answers, but at least I have some insight why this is there.
Comment by monegator 2 days ago
Comment by bayindirh 2 days ago
Debian has an extensive toolchain to check things. Having a set of deterministic tools which feed LLM with data can be beneficial, though.
Again, I'm not defending the LLM here, just want to show how hard the problem is to begin with.
Comment by khaelenmore 1 day ago
If there are deterministic tools involved - just return their output as is. It's usually quite readable if needs a bit of adjusting
Comment by pantalaimon 1 day ago
Comment by vitorsr 2 days ago
Comment by throwawayffffas 2 days ago
Sure LLMs are not nearly as rigorous about their output but that doesn't mean it's entirely not useful.
At a minimum you can have your LLM summarize the other LLMs output and go from there.
Comment by johannes1234321 2 days ago
LLM output may or may not be relevant, may or may not tell me something new and by the way it is structure is often hard to quickly oarse for the relevant piece in a wall of text.
Comment by pantalaimon 1 day ago
It does not have to be a wall of slop, maybe you only used LLMs 2 years ago where this would have been all you'd get.
Comment by pantalaimon 2 days ago
Comment by monsieurbanana 2 days ago
A script is reproducible, and fixable. They won't waste your time hallucinating issues. Note that this is different from "being wrong". A script can be wrong, and you can spend time debugging it, but that time is not wasted. You can fix the script, remove wrong rules, whatever.
Also, nothing exists in a vacuum. Script-generated review comments were never a widespread societal issue, LLMs unfeterred content generation is.
Comment by simias 2 days ago
Not even convenience at times, I think that for some the amount of technical-sounding text LLMs can output on demand is comforting. It feels serious. It feels like it's doing something important.
Meanwhile the rest of us have to deal with these low-signal/high-noise walls of text in commit messages and PR comments. Or ask another LLM to summarize them, I suppose. "Doing and undoing, it's all work", as we say in French.
Comment by jawilson2 1 day ago
Comment by bigstrat2003 1 day ago
Comment by pantalaimon 1 day ago
What makes you so sure that this is not the same thing?
Comment by Grombobulous 2 days ago
I think it’s actually very similar to a script. It takes an input and produces an output. Certainly it has more variation than a traditional script, but it's generally going to return a very similar answer when the same input is given repeatedly, like when you ask an employee at a restaurant where the bathroom is. The verbiage may not be the same every time but the answer is always the same.
Comment by joshstrange 2 days ago
- Slow PR review
- Nitpicks on style, not substance
- Async waiting for review or re-review after making changes, harder to stay in what passes for a "flow state" nowadays
- A lot of a ceremony around straightforward changes
We use LLM reviews at my company and it's caught things human reviews have not (as in in the early days we human-reviewed code and then did tests running the LLM afterwards and it caught things we didn't). It can review code at any time of the day and re-review it just as quickly as you can address the feedback.
I predict we (my company) are less than a year out from having a fully automated pipeline for reviews with only humans getting called in when it touches certain parts of the code. We already have a crude system for detecting certain file paths that we want a human to review if touched and we tweak that list over time as needed.
Comment by ImPostingOnHN 2 days ago
> Nitpicks on style, not substance
> Async waiting for review or re-review after making changes, harder to stay in what passes for a "flow state" nowadays
> A lot of a ceremony around straightforward changes
Those aren't great, but you what I like even less?
- Wall of nondeterministic bot text spam that may or may not be correct.
- Bot output has not been verified for correctness by the person who set up this bot output pipeline.
- Bot output has not even necessarily been read by the person who set it up.
- You have 24 hours to respond to this 5 page wall of text which may or may not be correct, or even make sense, or you will be penalized.
An appropriate response to this might be a reply flatly claiming that, actually, there aren't any problems after all, but that nobody has checked that that is true, and it is incumbent upon a human reviewer to verify your claims, like it was incumbent upon you to verify their bot's.
Can an LLM catch some errors? Absolutely. Can it be trusted to be correct absent review of the output? Absolutely not. So the simple solution seems to be, a human reviewer is free to run an LLM against code to review, on their own computer, and then they review the output, and they post the output only after verifying its correctness, taking personal responsibility for any issues with their posted output.
Comment by RHSeeger 1 day ago
And the person that wrote the code is expected to be the review.
Unless it's an automated pipeline that fixes the things found - I'm not a fan of that unless it's made VERY clear the LLM needs to be VERY sure it's right. And even then, I'd prefer it go through a human to decide which things are valid, then send them off to be fixed.
Comment by Roark66 1 day ago
Github copilot review is s great example of the worst possible way this can be misused. It is the worst waste of tokens there is.
Instead we use a process we created ourselves that runs opus or sonet (depending on complexity) to do a review (taking into account pr description and comments - copilot ignored those) and then to re-review the issues found to cut out BS.
This has been working very well mainly thanks to the prompts and docs we made it read, as well as us having lots of example code that shows how things should and should not be done.
One crappy thing Github does is that it doesn't allow our workflow based review's tokens to be accounted to individual PR authors like "copilot review" does, but accounts tokens to the organisation. It is obvious they are trying to herd people to using gh copilot review instead. But the quality difference is like night and day. So we are staying.
Comment by joshstrange 1 day ago
We also settled on a custom solution for reviews. We started with reviewers that claude/codex on GH actions and those were "ok" but kind of dumb and hard to tweak (GH Actions is just miserable to debug/iterate on). We still use them occasionally (@tag them to kick off a review) but we've shifted to a piece of software that we wrote that watches GH PRs and once certain labels have been added and the ticket in our ticket tracker (not GH issues) is marked as "Ready for Review" it kicks off a review and it reviews _all_ the PRs connected to the ticket. We don't have a monorepo, yet, so a new feature might span 3-4 repos (server, client1, client2, ...) and we want that work reviewed together.
We are close to having our review code spin up a fully isolated devstack running all our, many, services so it can poke around in the UI and write custom playwright scripts to test the new functionality. We have the devstack VMs working, just gluing the last of it together, it's pretty cool to see it all come together.
Comment by othmanosx 1 day ago
Comment by joshstrange 1 day ago
Personally I have an agent review the feedback and break down each item so it’s easier to review (helps remove some of the jargon/short-hand that agents use sometimes). Then I decide what to have an agent address and what to push back on. Like I said, I’m working on finding a way to automate part of that but haven’t settled on one I like yet.
Comment by othmanosx 1 day ago
Comment by eivindmeyer 5 hours ago
Comment by cedarbyte482 1 day ago
Comment by hypfer 2 days ago
It just needs ca 5 seconds to realize "oh damn, I would not want to be at the receiving end of this" and conclude that it's probably a bad idea.
Why does this keep happening?
Especially since the idea of having such automated reviews probably isn't bad. But why mess up the execution like this basically every single time?
Comment by throwawayffffas 2 days ago
The way I see it the devs that put that in place are saying, listen before even reading your contribution I am going to feed it to a LLM with these instructions and see what it spits out. Now I will extricate my self from being the LLM proxy so you deal with this output and when it's okay I will look at it.
Same as "listen bud until it passes linting I won't even look at it." Just a much more flexible and fuzzy linter.
Comment by hypfer 2 days ago
It's just such an obviously terrible execution. Why would you throw it into production when doing literally anything else - and that includes just setting the whole server on fire - is less damaging.
(Not hyperbole. Loss of trust and loss of trust in ones own judgement is the highest and harshest price in this industry)
Comment by InsidiousWombat 2 days ago
Comment by Roark66 1 day ago
So we setup llm based reviews that catch 99% of simple problems saving us 7 out of 8 rounds of PR reviews.
Seriously. Even as simple rules as: - if you submit a PR with new X, put a link to a successful run of said X to proove it's working. - if you choose not to reuse Y, but create a new one explain why.
Those are 100% ignored by people (or their crappy LLMs more likely - so I have to teach them how to prompt, or tell them which models to use for what).
Instead of loosing sanity responding for the 10th time to someone in time zone 12h away that he tries to merge reimplementation of what we already have with no description and no test run I have an automatic llm review that tells them that exact thing 2min after they create the PR.
Comment by samay-calidad 23 hours ago
Comment by MisterMunchkin 2 days ago
Comment by DaSHacka 1 day ago
My most recent experience was calling AT&T because the serial for my modem was whitelisted on an incorrect PON port (AKA the issue was on their end), yet if you correctly answer all the automated bot questions when calling their support line indicating you have an issue with WAN connectivity, it guides you through the process of unplugging your combo unit, waiting 10 seconds, and plugging it back in, then it automatically hangs up on you. Like thanks, that may help Sheryl who thinks the internet is down because her computer's DNS caches an expired facebook IP, but I literally cannot solve this issue myself without help from an AT&T tech lest I violate federal law by breaking into their network closet and do it myself.
I finally got through to a person by incorrectly claiming there was a billing issue and asking that rep to transfer me to the right department, skirting the bot entirely.
Comment by jrmg 2 days ago
But with the very latest models (like, Opus 5.5 class and up), I am now of the opinion that the output, in non-creative situations like code review and most software development, is fine. Great, even. Better than the reviews a lot of humans generate.
Honestly, if you’re at all open minded about this, get a $20 Claude Pro subscription for a month (they are easy to cancel) and ask Claude Code with Opus 5.5 to review your codebase or a PR or two. I was very (pleasantly? unpleasantly?) surprised.
I have complex emotions about this (‘sad’ on balance I think - although it’s definitely not all simply in that direction), but I can’t deny it to myself.
I still bristle at reading articles and even documentation that’s not just ‘reference’ documentation written by it - and even that can get a bit weird and circuitous. But for review and coding? It’s great.
Comment by hypfer 1 day ago
Comment by jrmg 1 day ago
I thought this was the crux of your argument. What did I miss?
Comment by hypfer 1 day ago
Comment by slybot 2 days ago
GR resulted in Proposal E, Choice 5: Responsible Use of Generative AI. Clearly stating: "Any such automated process should be overseen by a human who remains accountable for its behavior and output."
Comment by baumschubser 2 days ago
Comment by Tade0 2 days ago
It became actually useful only with the advent of Opus 5 and its competitors. Nowadays it usually makes a few good points, but in instances where it doesn't, it's quite the stubborn asshole.
This one time I had to paste a function from a library because it couldn't get it to its digital head that its assuming the function has a certain implementation based on its name only.
Comment by Grombobulous 2 days ago
What will it be like in 6-12 months?
Opus 4.8 came out in May of 2026, 5 months ago.
Comment by flir 2 days ago
/* @code-review ignore */ [...] /* @code-review endignore */
I mean you shouldn't have to, but I'm wondering if you can.
Comment by gbuk2013 2 days ago
Comment by jawilson2 1 day ago
Comment by shawabawa3 1 day ago
LLMs sprinkle comments everywhere, and they are completely pointless because no human is going to read the code and an LLM can recreate the comment by reading the code anyway
Comment by flir 1 day ago
Comment by RetardedBastard 1 day ago
Comment by eivindmeyer 5 hours ago
Comment by toaste_ 2 days ago
Does not respect the maintainer's time: DSFG uses an LLM to automate reviews. It auto-replies to submissions. There is an appeal process to theoretically handle errors.
The crux of polite LLM use is on whom the burden of the flood of generated output falls.
If you are the consumer of your automated output, all good. Say you generate a report and read it, the burden of inaccuracy or verbose output generated in seconds falls on you. Not only does this avoid wasting other people's time, you have the power to go fix the tool to stop wasting yours.
If the output goes directly to others, the burden of correcting inaccuracy falls on them. The burden of reading it falls on them. And they usually then have to scale some wall of automation to reach a human and convince them to fix it. Users subjected to this will be rightly pissed off.
Comment by tommica 2 days ago
Lesson for us all is that if we do not own the thing/project/etc, things can suddenly change without our decision, and all time we put into it might become a waste-of-effort retroactively
Comment by jewel 2 days ago
https://www.debian.org/devel/constitution
It sounds like in this case someone is not following an agreed-upon policy. And of course, even with governance like this one, the rest of the maintainers can move in a direction you don't agree with.
Comment by lukeify 2 days ago
Comment by throw-qqqqq 2 days ago
I contribute to open source software because it improves stuff I use and/or care about.
It seems too pessimistic, IMO, to abstain because things could potentially change to the worse, sometime in the future.
Comment by sampullman 2 days ago
Comment by throw-qqqqq 2 days ago
Patience and persistence helps, but it can be daunting IMO
Comment by poszlem 2 days ago
Comment by throw-qqqqq 2 days ago
I replied as I did, because lukeify implied that lack of ownership is
> one of the primary reasons I can never get interested in contributing to open source
Comment by calvinmorrison 1 day ago
Open source is open source. publishing code.
it does not mean
- you need to respond to peoples PRS
- it does not mean you need a github
- it does not mean you need to provide ANYTHING to the user. No warranty.
- you do not need a mailing list
- you do not need governance
Do what you want, have fun, if you have peers or other people interested in your area, feel free to collaborate in the same way you would with pickup basketball at the park, play, have fun, and leave when you're done.
Comment by louwrentius 2 days ago
There is no alternative to Debian for me. I’m ready to justy throw out all my computers and become a goat herder at this point.
PS I’ll remove memory and storage from said computers to pay for land and goats before I chuck them out of my window.
Comment by RunSet 2 days ago
Comment by frou_dh 2 days ago
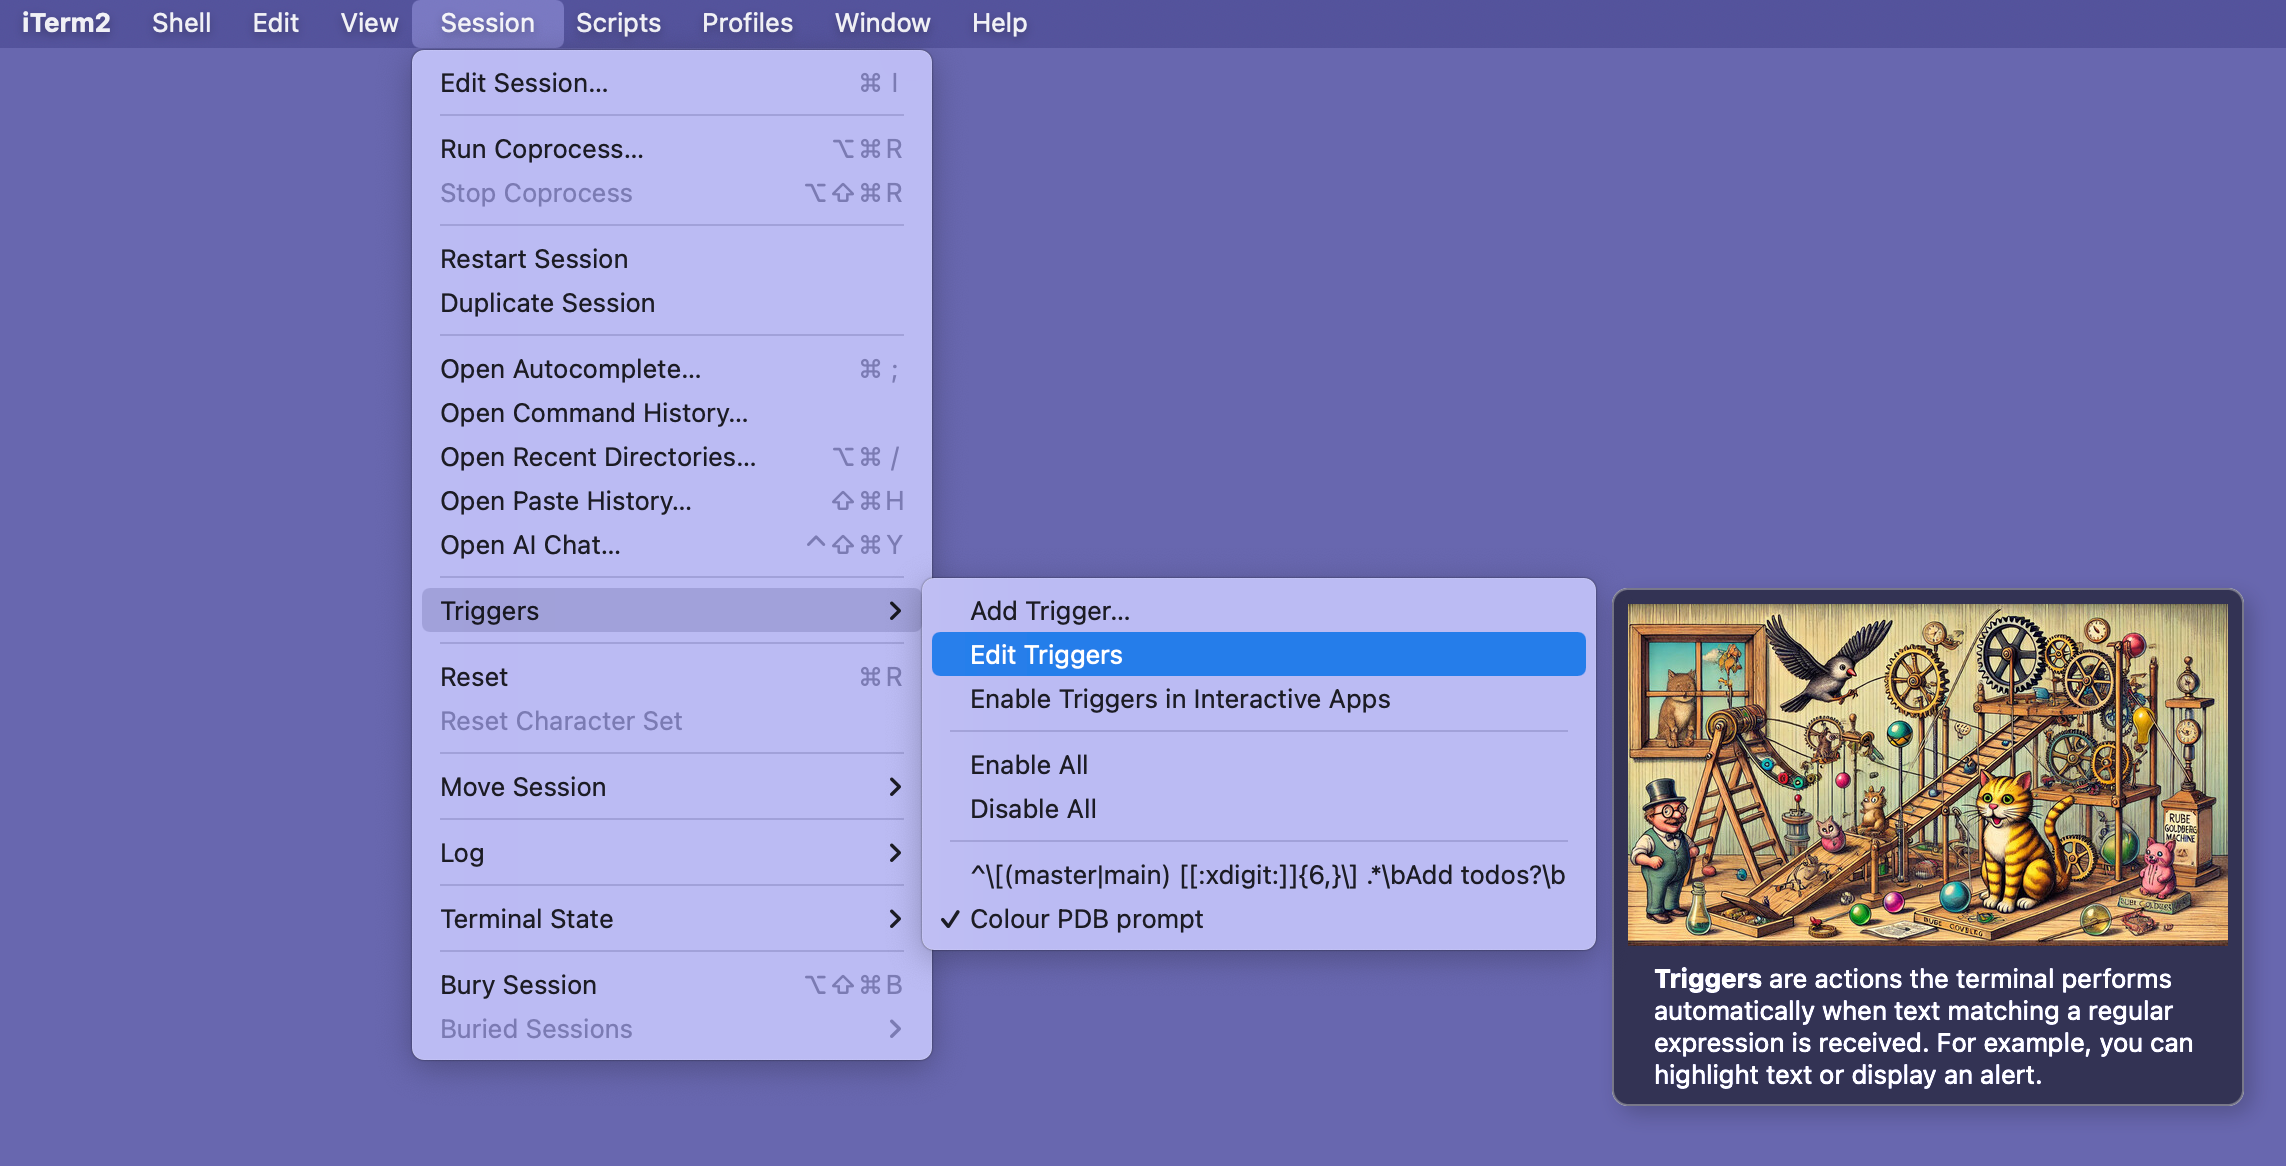
In recent versions of iTerm2 for example, when using the plain old menubar and hovering over some items, panels appear showing awful sloppy AI images. WTF? https://files.catbox.moe/5ivkhw.png - That makes me question everything... Was the developer always tasteless? Or did they get a taste bypass?
Comment by meindnoch 2 days ago
With AI, creating the tasteless thing became easy.
If you give people the ability to select a font, they will select Comic Sans.
Comment by mrob 2 days ago
Comment by wyclif 2 days ago
Comment by rf15 2 days ago
Comment by alex_suzuki 2 days ago
Comment by superdisk 2 days ago
That AI image is pretty baffling though. Setting aside the pointlessness of displaying an image in the context menu, it even looks like it was made with ancient stable diffusion from 2024 or something, modern image generators are "better" than that. I wonder when it was put in.
Comment by vunderba 2 days ago
Then they proceed to summon a million infernal imps.
Comment by account42 2 days ago
Comment by hypfer 2 days ago
I've never considered updating iTerm. Apparently that lazieness was the right call?
Jesus. What the hell. What does that sudden AI image even offer? I guess it would make some sense in a "docs page" context (even though there it would too be slop), but as a tooltip of a menu option?
Gotta say though.. that is so unhinged, one has to respect the human ingenuity behind it. No LLM can come up with an idea so batshit insane. They're too mid for that.
Comment by tjpnz 2 days ago
Comment by vconnor 2 days ago
Picking at random a successful and unsuccessful LLM-generated review from the dashboard, the successful review consists of 734 words (~2.5 printed pages) and the unsuccessful review weighs in at a whopping 1,535 words (~5 printed pages). I haven't tried to fully read either report, nor spend brain cycles checking if the LLM output is legitimate or not. I just want to emphasize the many orders of magnitude change in review size that's being generated, and that uploaders may need to spend time trying to review and understand in this new process.
A bit rude to expect people to swallow 5 pages of slop to figure out why review failed.
EDIT: made my comment more constructive, but originally asked if any distro has adopted a hard anti-AI stance.
Comment by BSDobelix 2 days ago
Yes all the BSD's, and i think with the best explanation, since one cannot proof what license the llm's output has, one cannot legally implement the output under the BSD-License.
But what about Linux? They just dont care, they have the money, corporate backing and with that, all the power.
Comment by account42 2 days ago
Comment by BSDobelix 2 days ago
Comment by none_to_remain 2 days ago
Comment by vconnor 2 days ago
Linux itself is in any case tainted, but some of us care to contain the plague however possible.
Comment by account42 2 days ago
Comment by DaSHacka 1 day ago
Comment by bigfishrunning 2 days ago
Comment by Grombobulous 2 days ago
It does have very strict standards, but AI is explicitly allowed to be used in the aid of development of the Linux kernel.
You can't be hard-no-AI as a Linux distribution because it would be like having a vegan car company where the seat supplier used leather. You'd have to fork the Linux kernel from the last version that was developed before LLMs were adopted, or write your own kernel.
Comment by znpy 2 days ago
Comment by RHSeeger 1 day ago
I don't feel the need to make someone else read the LLM output first just to do an inferior job than what I would do (since I know the code and can more easily identify what is valid vs what isn't).
Comment by doginasuit 2 days ago
It seems like the question is where to fit it in to the pipeline. The team responsible for reviewing submissions could leverage it to speed up the process, and still respond personally.
Comment by KolmogorovComp 1 day ago
They can stop, it does not matter, there will be others ready to contribute.
It is a ruthless reality but you have to preserve the most precious resource in FOSS which currently is maintainers.
Comment by boredhedgehog 2 days ago
Comment by iugtmkbdfil834 2 days ago
The question is not even about the setup in terms of hardware/software. The question is about organizational structuring of its processes.
Comment by Grombobulous 2 days ago
Comment by toenail 2 days ago
Comment by gilrain 1 day ago
Comment by cadamsdotcom 2 days ago
Even something as simple as writing the phrase "No LLMs please" somewhere in the upload, that if present, prevents LLMs being triggered. Nothing elaborate and it preserves the default-on behavior the team seems to want.
Comment by philipwhiuk 2 days ago
The problem would be better solved with an opt-in.
Comment by silveraxe93 2 days ago
> I will not upload anything to NEW unless there is a way for me to opt out of this. I would prefer if the default was "no LLM review" and that developers have to explicitly opt-in to receive an auto-generated review.
Comment by voakbasda 1 day ago
I wager the resulting usage would drive the system costs up to the point that it would be dissembled and decommissioned. That only happens if the people behind it feel the cost personally.
Comment by Roark66 1 day ago
I was migrating cicd from Jenkins to gh workflows for some 70-80 apps each in its own repository and support team in a random timezone. I had to open 2-3 PRs in each repo and a day or two before someone enabled "copilot reviews" in our github org.
Not only did copilot eat up all my bloody llm credits (thankfully it was almost end of the month) it created few silly comments on each of those PRs I had to respond to.
So I used an llm to write a script to respond to each of those and close them.
Also the same script wrote emails to all the teams asking for approvals, sent reminders to those that ignored it over next few days and finally merged everything in the right order.
Overall I'm a big fan of properly used LLMs.
Comment by voakbasda 1 day ago
It is a shame that Debian has invited such behavior by this move.
Comment by disiplus 2 days ago
Comment by monsieurbanana 2 days ago
Comment by voidUpdate 2 days ago
Comment by tempfile 2 days ago
Comment by bArray 2 days ago
    a) spend my valuable developer time (this is my free time) on reading machine
    output which indeed might be completely wrong and get angry and upset for
    reasons which have been listed in great detail by those opposed to LLM-use in
    Debian on debian-vote

    b) not read the machine-generate review and have the resources that were
    required to generate it not only be wasted, but let my upload become another
    item in a statistic which shows how many tokens Debian is using up because the
    more tokens we use the better our software, right?
Comment by silveraxe93 2 days ago
> I will not upload anything to NEW unless there is a way for me to opt out of this. I would prefer if the default was "no LLM review" and that developers have to explicitly opt-in to receive an auto-generated review.
But as the system stands he only has those 2 options. Which is why he will not use the system until they add a 3rd one.
Comment by bArray 1 day ago
Comment by Pavilion2095 1 day ago
Comment by viraptor 2 days ago
But it looks like the team decided to shoot themselves in the foot there and both implement and communicate the change badly...
Comment by zzzeek 2 days ago
> I rather wait a year before my package makes it through NEW (yes, that happened) than have my strong opposition to LLMs be ignored and all my uploads being automatically screened without my consent.
so those entries go in the "abstain-from-LLM-queue", where there is no guarantee of timeliness at all, and human volunteers can process that queue manually as they are available
tldr just tag the entries as "OK for LLM" or not. it's just like organic and non-organic produce, it can be done.
Comment by VortexLain 2 days ago
Comment by WesolyKubeczek 2 days ago
That said, the LLM presence and involvement should be confined to the team using it. "We don't know what it says, it is not a part of judgement, it may make mistakes, but here's a wall of text from it for you to read for who knows what benefit" is quite a dick move. Don't throw slop into people's faces like that.
Comment by eur0pa 2 days ago
> I do not believe that it is reasonable to ask people to spend time on an unreviewed LLM output. If it was too much work for the DFSG team to read it then it is for me as well. I do not object in principle to the use of a LLM, but the DFSG team needs to take full responsibility for its output: this kind of disclaimer is not acceptable.
Once again, human attention and human effort, etc
Comment by mono442 2 days ago
Comment by tiahura 1 day ago
Comment by vinyl7 1 day ago
Comment by ritwiksrv237 1 day ago
Comment by voidmoth 2 days ago
Comment by rurban 2 days ago