The Goose Programming Language
Posted by bobbydigitales 4 days ago
Comments
Comment by Aardappel 4 days ago
Comment by adastra22 4 days ago
Comment by assimpleaspossi 4 days ago
Only on the Internet is this true, not in real life. I cannot and do not trust any of these things to do a proper job because they have not in any situation succeeded in any job I've given them. And no company I deal with claims otherwise
Comment by Krei-se 4 days ago
- You need to have a mental model to grow an idea
- When a pattern is known you can use a library!
- When a pattern is not known AI will make stuff up
No matter how "good" coding with an AI will become there is no way you get around learning, having someone understand what's going on and take responsibility.
I'm fine with formal checking and fuzzing or getting hints where a bug might come from - but these are iterations on tools we used before like a debugger, strict types, functional programming and well fuzzing.
I tried to have an AI iterate on a step i don't fully understand yet and i always regretted it. Highly interconnected projects will grind to a halt until you do learn.
You can check with people doing highly specced software in the medical domain that even with very good specs there is ambiguity in natural language thus it can never be the source of reliable and manageable software.
However - i read about some smart guys in the 40s or so encountering the need for a formal language to tell a computer what to do with 0 ambiguity and i think they called it a "programming language"
Comment by lilbigdoot 2 days ago
I had to accept this one too even for pretty simple things. I had an LLM wire up a neovim connection handler for me without bothering to read the libraries docs or neovims RPC spec and I completely regretted it. You would thing such a small piece would be fine but I couldn't work on it and had to rip it out and rewrite it, and reading the AIs reference code actually got me more confused than anything.
I've found the sweet spot for me is just writing code and promoting an AI whenever I have a question or if I'm not sure the code will do what I think. When I hit a point and I groan about doing something, if it's small and I understand what needs to happen already I will ask the LLM I've been prompting already to do it. Usually by that point it's already gotten enough context from the back and forth on my questions or me explaining assumptions it got wrong when reviewing my code.
Comment by lilbigdoot 4 days ago
Still glad I basically never have to debug a build issue or memory error again though
Comment by avadodin 4 days ago
Lack of documentation used to be a running joke.
The goose_spec.txt in 2019 would be "goose is like c and rust only with syntax like array{;}[] btw it uses a small amount of stacks instead of malloc."0 10klocs.
Now, we make sure the AI leaves documentation so it can figure out what it was doing earlier.
A local model a few generations and many weights behind newest Claude can implement my novel algorithms and write the documentation I wouldn't.
Yes, many times it does dumb CS for kindergarten mistakes but it only has to work towards the optimum every once in a while.
Comment by hexasquid 4 days ago
Comment by b33l 4 days ago
Comment by slopinthebag 4 days ago
Comment by f0e4c2f7 4 days ago
It might make sense to learn now, before everyone expects that you be an expert with this tool in order to do your job. On the other hand perhaps they will be easier to learn if you wait.
There is an incredible amount of nuance to be had in using LLMs and we reached the stage, probably only in the last few weeks where all the pieces have fallen into place such that if you are skilled at using the LLMs just about all of the previous problems with them can now be easily mitigated. If you learn how. There is a lot to learn.
Comment by jonenst 3 days ago
"we reached the stage, probably only in the last few weeks where ..." This has also been said every other month since 2023.
Comment by f0e4c2f7 3 days ago
Personally I disagree with this. I've been using LLMs the last few years and learning a lot about techniques for getting value out of them. Even though they weren't very good for a while they seemed worth learning to me because the rate of improvement was so fast. We've now reached a point where if you know how to use them right you can get lots of value out of them.
I really don't mean to be rude here but consider perhaps the reason why you're having trouble seeing why they're valuable is because you haven't used them enough in the last few years or kept up with the developments closely enough. Maybe I'm wrong. But consider it's possible you are too.
> This has also been said every other month since 2023.
I'm sure others have said that but my perspective has been that the models are not quite good enough yet, for a while but that the trajectory is so crazy that it made sense to make the bet and invest lots of time into learning how to use them on the assumption that they would soon be good.
Even now I would say they have a long way to go. What is hard but possible today will be easy tomorrow. But quite a lot is now possible with the right techniques. Crazy things.
Comment by johnisgood 3 days ago
Comment by jazzypants 3 days ago
It really is like working with an over-eager employee. They just also happen to be a pathological liar.
Comment by thin_carapace 4 days ago
Comment by f0e4c2f7 3 days ago
Comment by thin_carapace 3 days ago
Comment by behringer 3 days ago
Comment by tocabocaapk 3 days ago
Comment by fizzbuzzbarbazz 3 days ago
Considering that I don't know rust at all, it's awesome.
Comment by prajaybasu 3 days ago
Comment by incrudible 4 days ago
Comment by polski-g 4 days ago
Comment by adastra22 4 days ago
Comment by rocho 3 days ago
Comment by adastra22 3 days ago
Comment by pphysch 3 days ago
Comment by Archer6621 3 days ago
That said, I do genuinely enjoy brainstorming with it, and these quirks are not really a hindrance. If anything, the sentiment in the first paragraph is quite useful to quickly get an insight about where I stand with my thoughts, relative to the available knowledge that Gemini has access to.
Comment by dirkt 4 days ago
With the tutorial, the summary also makes more sense. I have not read the other parts yet, but so far I like what I see.
All is in pretty good taste, and I like what I've seen so far. I do not care if the author himself came up with the idea, or if AI came up with it and the author approved.
I do not understand why you "have to" know this to make use of it. You can judge ideas independently of where they came from (and you should).
Comment by discreteevent 3 days ago
You can but in practice nobody does this because they don't have time. For example, once you have investigated ideas from a crank a couple of times - you don't do it again. Life is too short.
Comment by catlifeonmars 3 days ago
Comment by ckx 4 days ago
Comment by shmageggy 4 days ago
Couldn’t make it more than a few sentences in before the bile started to build up in the back of my throat and I had to back out. It’s shocking to me that people knowingly post unedited Claude-slop drivel and are seemingly unashamed about it. In 2026, it seems the main role of technical humans should be to act as a barrier between our agents’ output and other humans.
Comment by asohal 3 days ago
Comment by WillAdams 4 days ago
Apparently, this can actually assist the LLM:
https://silly.business/blog/we-should-revisit-literate-progr...
as discussed here previously:
Comment by elxr 4 days ago
I'd love to experiment with this myself.
Comment by WillAdams 4 days ago
https://www.goodreads.com/review/list/21394355-william-adams...
Note that ICC, a C compiler, is one:
https://www.goodreads.com/book/show/522102.Retargetable_C_Co...
Note that one can look through projects tagged as Literate Programming by using the topics view:
https://github.com/topics/literate-programming
might be there's something useful there.
Comment by cmontella 3 days ago
There is! As of now, if you sort by recently updated, my literate programming project is the first result :P (link in profile if anyone reads this later)
Comment by WillAdams 3 days ago
Comment by johnisgood 3 days ago
Comment by felixgallo 4 days ago
Comment by spuz 4 days ago
That's without even mentioning that AI writing can often state the what but not the why. That human perspective is usually the most valuable knowledge to get across in writing.
Comment by JojoFatsani 4 days ago
Comment by foltik 4 days ago
Of course Humans can make errors when translating that to English. But if you’ve read any amount of Claudish it should be obvious that interpolating the code to documentation with an LLM typically produces a significantly worse result in almost every way. Except for superficially “sounding” correct.
Comment by brabel 4 days ago
Comment by jug 3 days ago
Comment by vikramkr 4 days ago
Comment by creata 4 days ago
Plus, if a human puts the effort into writing something, that signals to me that it's worth something, because human time is much more scarce than LLM time.
Comment by lilbigdoot 2 days ago
Within the first couple of paragraphs and bullets it made a completely false claim that is the opposite of how the language operates, something any person that knows the essentials of it would know. Language Y was listed in the front page as an inspiration (and I don't doubt them) but clearly they either did not read the docs the LLM wrote or did not use the language for long enough to know it has zero structural typing
Comment by ashkankiani 4 days ago
Comment by conartist6 4 days ago
If you believe you are making something worth other people's time, you should ALSO believe you are making something worthy of your own time.
Comment by partyficial 2 days ago
would you fly in an airplane if the software was written mostly by Claude?
If an engineer who mostly used Claude left the company, can his replacement understand his mental model, given that he himself doesn't ?
Comment by vikramkr 4 days ago
Comment by adastra22 4 days ago
You cannot tell either from the AI written docs. I'd rather OP gave a rambling post about some problem he has in gamedev that led him to think a new language was needed, why the constraints are different, and how this will improve X, Y, or Z in his own words. Then I can infer what this project is and where it is going. Right now, I have no clue.
Comment by felixgallo 4 days ago
The author has written that post about why the language came about. He doesn't owe you that, but he did it anyway. He doesn't owe you anything more. You can use it or not. Advising him to throw away all the documentation and rewrite it again by hand from scratch so that adastra22 can deign to examine it further is ridiculous.
If you have a question about whether or not this further iterations will fit your specific (and so far undescribed) particular use case, the correct avenue for that is to ask the author politely. Or Fable; Fable could probably tell you without having to bother the author. But holy cow, the entitlement.
Comment by adastra22 4 days ago
We're talking about a programming language. Languages, and their compilers, evolve over time. Where is this one headed?
Comment by vikramkr 4 days ago
Comment by adastra22 4 days ago
If this is your default assumption, I hope I never have to rely on code you generate.
Comment by vikramkr 3 days ago
Are we losing our accumulated engineering best practice knowledge? Yes. Have you seen the quality of new hires recently? The ones who've cheated their way through school and don't know what a for loop is? People that have those skills aren't letting them atrophy but the chain of transmission is in crisis. Breaking news, sometimes things suck
Comment by baq 4 days ago
Comment by felixgallo 4 days ago
The way to find out if a language is suitable for your needs is not to demand, in an entitled way, that the author perform an act for you. It is to (a) ask the author politely; or, failing that, (b) to examine it yourself (or ask Fable to evaluate it, using tokens you paid for).
This particular language, further, is Apache 2.0 licensed. If it's not working for you, fix it. Jesus.
Comment by knowsuchagency 4 days ago
Comment by adastra22 4 days ago
Comment by partyficial 2 days ago
"Faster than C++ and than safe Rust, ..."
perfectly legible ?
Comment by vikramkr 4 days ago
Comment by hexasquid 4 days ago
Comment by condwanaland 4 days ago
Comment by hackrmn 4 days ago
Comment by elxr 4 days ago
For a programming language? It's subpar and you know it.
See this for a language docs site by a small-ish team, but a significant effort was put into making it nice to read: https://tour.gleam.run/everything/
Comment by otabdeveloper4 3 days ago
That's, like, a stunningly low bar for documentation. "The vehicle is perfectly capable of performing motion, why are you complaining?"
Comment by nozzlegear 4 days ago
This one is easy: I'd read the docs if it were written by a human, but I won't read them if they're written by Claude.
Comment by fuzzythinker 4 days ago
Comment by fasteo 4 days ago
Comment by emmelaich 4 days ago
Comment by tymscar 4 days ago
Comment by vermilingua 4 days ago
Comment by netless 4 days ago
Comment by koolba 4 days ago
> Nested data stays inline. A string, an array of strings, a record with variable-size fields and an array of those records are each one contiguous block with no pointer in it. A record that is 160 bytes and an allocation in C++ is 29 bytes and none in Goose.
I’m having trouble parsing that last sentence.
Comment by Aardappel 4 days ago
Even Rust's "enum" feature, which can store different sized things all in the same space, does that at the cost of the smallest variant being just as big as the biggest.
Goose can do all of that not only inline (no pointers), but with variable size, meaning small items take less space. It's like a serialized data representation, but iterable. It makes for big space savings vs these languages.
Comment by eslaught 4 days ago
Doesn't that waste a lot of space? Or is there something I'm missing?
Also it would seem to force every allocation to go through the OS kernel to allocate unless there's some trick to avoid that.
Comment by vanderZwan 4 days ago
For example, suppose we have a function with a growable array that calls another function (without passing said array) that also uses a growable array as some temporary scratch space. Then the first function's array isn't being used when the second is sleeping, so the inner function's array could safely share the stack because it will all be freed with a single pointer restore once the second function exits.
Now, I actually don't know how the compiler works but as I understand it does things similar to my example to optimize the number of stacks needed (but let's wait for WvO to confirm or deny whether my understanding matches reality).
Comment by Xirdus 4 days ago
Comment by dirkt 4 days ago
You can just store all them items of the list/tree/whatever on the stack, growing it as needed, or you can add an addition "freelist" for a particular stack, so you can re-use items.
Comment by cardboardguru 4 days ago
Plenty of trees only ever grow. And that's the normal type of array in Goose. However you can also have arrays that can grow and shrink, if you have a tree that is constantly in flux.
Either way it'll be one stack for an entire tree.
Comment by Aardappel 4 days ago
How you deal with the inner stack growing depends, ideally they don't grow (construction only), or you can make them fixed size, or with a capacity, or in the worst case, as a pool. The language has facilities for all of these.
Comment by cardboardguru 4 days ago
Comment by adwn 4 days ago
No, you can typically only assume 48 bits of virtual address space; the kernel takes half of it, so really only 47 bits. Newer CPUs provide 57 bits (e.g., Zen 4) or 52 bits (certain ARM64 models). And that's provided that the kernel plays ball; apparently some Android configurations only support 39 bits of user virtual address space.
Comment by koolba 4 days ago
Comment by mgaunard 4 days ago
I have both what I call inline sequences, and out-of-line ones (store an offset to the object itself rather than pointers).
I made all my sizes and offset 32-bit, but I suppose they could have been 16-bit.
Comment by groundzeros2015 4 days ago
Comment by randfur 4 days ago
Comment by lynndotpy 4 days ago
So, I read it as, "C++ uses 160 bytes and an allocation, when Goose requires 29 bytes and no allocation".
Comment by nextaccountic 4 days ago
how to perform this copy without atomics?
do the workers run as threads or processes?
also you claim it's faster than rust and c++. but for certain kinds of software it's certainly (and substantially) slower, right?
Comment by Aardappel 4 days ago
The workers are threads. The separate memory is the concurrency model, but it's still single process, multiple threads.
The "faster than" is on average, and both in my own benchmarks and independent benchmarks you can find examples of algorithms where it is slower, but they tend to be the exception. "substantially" slower I haven't found yet.
Comment by nextaccountic 4 days ago
Well message passing with literal memcpys (rather than, say, just a shared buffer, like is common in Rust) is very expensive when the messages are huge. Of course as the message size increases, the Rust program will become faster than the Goose one (and if it doesn't, you should look into your benchmarks)
Being more specific, it means that for each message, we are writing on memory twice - one to build our own buffer with the message, and another to make a copy to another worker. Message passing violates, in spirit, the Goose rule that things are built on their end destination: we can't write into a buffer owned by another task, so we need to first write on our own buffer, and then do a copy, which is a lot like first writing the value to the stack, then copying the heap. Writing twice has an overhead, specially when messages don't fit in the cache - you just need benchmarks with sufficiently large messages to demonstrate it.
Beyond that, there are some algorithms that can be made much faster when written with atomics rather than message passing. (Also there are algorithms that will get faster if you use locks! Locks aren't always slower). It's just a matter of finding such examples, and writing a Rust code that will use atomics, compared to a Goose program that uses messages between workers because Goose doesn't expose atomics to the user.
So if you didn't find such examples, it's because you didn't specifically write benchmarks with those scenarios in mind (or, I mean, didn't told your LLM to write this).
That is: if the Rust program and the Goose program do the same thing in the same way, then it's reasonable that Goose is faster on average. But Goose is limited because it doesn't let you do some things, but Rust does, so to compare the languages you need to find those cases where the Goose limitations end up making the software slower
Comment by Aardappel 3 days ago
Note that all this supposed copying overhead also has an upside: once the synchronisation has happened, every thread can now run at maximum speed doing single threaded memory allocation with no locking of any kind.
In C++, malloc/new in multithreaded programs needs to essentially go thru a mutex and can make allocation even more expensive than it already is. I am not sure if Rust does the same.
Since in Goose "allocation" is just a pointer bump, we cannot make that multi-threaded, hence the threading model followed from that.
And like a lot in Goose, you have to write your program to fit the language a bit. If you expect to do concurrency on top of a huge graph of constantly changing data that all threads must have immediate access to, it is probably not the language for you. But there are plenty of concurrency models that fit and are blazingly fast.
Comment by Jtarii 4 days ago
Comment by cardboardguru 4 days ago
Comment by AnEro 4 days ago
Comment by Aardappel 4 days ago
Once the initial compiler was there it became easier, as Fable is rather good of working within the context of what is already there.
Comment by AnEro 4 days ago
Comment by dananabread 4 days ago
Looking at the repo it seems like the N stacks generated by the compiler are placed at least 2gb apart in virtual memory, have you run into any cases where that has been overflowed during runtime? The compiler cannot know which of the stacks are going to be used more than others and in a large complex program with many stacks any one of them could fail. I imagine this being an issue depends on target application - if you know you are building a game that you know the exact size of your levels / entity counts beforehand you know this is fine but if you were doing data processing / parsing potentially malicious user input it may be a problem.
I'm also interested how the memory locality works. Here you have the bases of your stacks at a series of very sparse virtual memory intervals which will be mapped by the page table to some physical memory addresses, does having them be so sparse cause any issues?
There are some unique ideas here - lifetimes on references to growable+shrinkable stacks, "balancing" stacks in recursive functions - and I'm glad you were able to use coding agents to actually materialize them.
Comment by Aardappel 3 days ago
I am not sure what issues could be caused by the sparsity. Like you say, all that matters is that in physical memory, we are only using what is actually in use.
Thanks! :)
Comment by Zecc 4 days ago
Comment by Aardappel 4 days ago
Comment by ashkankiani 4 days ago
That is about where our similarities end, though, since I'm doing quite a lot of other stuff in the midst as well (much heavier type stuff, fully incremental, retargetable, reflection, integer range tracking, blah blah blah), and the more goals you have, the complexity blows up exponentially. I do think that the region based memory part alone is worthwhile to have as a language feature, so I applaud your pragmatism. I like your syntax for returning through call stacks, too.
There are other languages that do this, though. Did you look into any of the others? Or ones like Odin which give you the configurable bump allocators and scratch space as well? Mainly I'm curious about your opinions of prior art.
Comment by ashkankiani 4 days ago
anyway, hope this project goes well! the secret of the arena allocator seems to be out now to the mainstream. I think this is also a strength of array programming languages in the tradition of APL/J/K/Q.
As this project develops, I'll get to benefit from your public crowd sourced testing and design before having to publicize mine :P
Comment by cardboardguru 4 days ago
Comment by giovannibonetti 4 days ago
Comment by Aardappel 4 days ago
Comment by opem 3 days ago
Comment by Aardappel 3 days ago
Comment by SwellJoe 4 days ago
Comment by peterashford 9 hours ago
Comment by Aardappel 4 days ago
Comment by JurassicTyler 4 days ago
Hows the compile time? Do you have a number or is it similar to another language?
Comment by Aardappel 4 days ago
Optimized builds go thru the local C compiler, so they are limited by the speed of that. Dev/test build can use the built-in libtcc JIT which is super fast.
Comment by avilay 4 days ago
Comment by Aardappel 4 days ago
Whether it would make sense in this AI world was not a consideration.
The syntax and semantics were mostly designed for humans. That said, using it optimally asks a lot of the human, and in turns out the better LLMs don't break a sweat using it, so maybe it accidentally hits the spot. Goose with LLM can give you lots of speed without the effort.
In some weird way it is a great time to make new languages, because the downside of convincing humans to learn it is gone. Anyone that has a project that needs to be fast can decide to use Goose for it at very little cost.
Comment by avilay 4 days ago
> I made this one because I had a really strong design in mind that I think should exist.
Comment by wvlia5 3 days ago
I like the XY language, what do you think? https://nsl.com/k/xy/xy.htm
Comment by Aardappel 3 days ago
Comment by wvlia5 3 days ago
Comment by ksec 4 days ago
Do you know if Goose is the first time something like this has been done?
Comment by Aardappel 4 days ago
There is lots of prior art on the individual parts of the design, e.g. "regions" and various stack languages etc, see: https://github.com/aardappel/goose/blob/master/docs/design/p...
Part of this is that 64-bit address spaces make this design practical, and almost all languages in use today were designed with the limitations of 32-bit in mind. Once you can assign arrays huge amounts of address space, you don't have to realloc, which gets you stable pointers, and a lot of the other Goose features.
Comment by amelius 4 days ago
I'm wondering what kind of architectural corners this forces the programmer into ... have you found any so far?
Comment by Aardappel 4 days ago
It certainly requires the programmer to rethink how they structure their data, as you have to think of where it is going to be stored, and how to store it in a way such that it will have similar lifetimes to what it is stored with, to get the most out of the language.
Comment by Zecc 4 days ago
Comment by Aardappel 4 days ago
Comment by fancyfredbot 4 days ago
How are you deciding how many stacks to use?
Comment by Aardappel 4 days ago
The programmer choose what to store where, so you typically store things in arrays by lifetime. Goose gives you many more tools to do that, it can store entire variable sized trees of an enum type in a single array.
You try to avoid having to deallocate in mixed/random order, but if you absolutely must, you can turn arrays into pools, basically.
Comment by fancyfredbot 4 days ago
I'm a bit confused about how you could decide the number of stacks at compile time. I can see you could see how many arrays are lexically in scope. However if the code puts one dynamic array inside another dynamic array I can get to an unbounded number of total stacks without ever needing more than two in lexical scope at once. Do you also add stacks at runtime? Like a stack of stacks?
Comment by Aardappel 4 days ago
Comment by fancyfredbot 4 days ago
The spec on your GitHub says: "Two simultaneously-live resizable values never share a stack."
So I surely can't have a dynamic array of dynamic arrays share a single stack? That's an unbounded number of resizeable values sharing a stack?
You could make it work on a single stack but that would involve having non-contiguous memory for each inner array since you can add to any array in any order.
The spec implies that we need one stack per element of the outer dynamic array which would let you have contiguous memory for each inner array, but you wouldn't know how many stacks you needed at compile time.
Comment by Aardappel 4 days ago
Depending on your needs you use one of these solutions.
Comment by fancyfredbot 3 days ago
Comment by mikeiavelli 3 days ago
Comment by Aardappel 3 days ago
Comment by erfgh 3 days ago
Comment by Aardappel 3 days ago
For details on how, see https://github.com/aardappel/goose
Comment by ModernMech 3 days ago
Also, to be transparent in your benchmarks you should compare against idiomatic safe code, and optimized code. It's trivial to throw your benchmark examples into an LLM and tell it to optimize them to parity with Goose. It's more trustworthy to show other languages can achieve the same performance, Goose isn't doing anything special there. What it is doing is doing the same with better safety guarantees, which I think is headline result not the speed itself.
Comment by Aardappel 3 days ago
As for the benchmarks, that's exactly what I do: https://aardappel.github.io/goose/bench/results.html
If you mean the other benchmarks (LangArena), I don't control their design.
Comment by ModernMech 3 days ago
> As for the benchmarks, that's exactly what I do
What I mean is the story of those benchmarks is incomplete, you're missing a column for optimized Rust. This is what I get on my M1 if I ask the LLM to write more performant (still safe) solutions to a couple benchmarks, I'm sure your LLM can do the same:
  | Benchmark | vs original Rust | vs optimized safe Rust | Memory vs original Rust | Memory vs optimized safe Rust |
  |---|---:|---:|---:|---:|
  | `sexp` (flagship workload) | 1.00× | 0.95× | 2.22× | 1.60× |
  | `records` | 1.52× | 0.54× | 4.77× | 2.58× |
  | `graph` | 1.24× | 0.75× | 1.00× | 1.00× |
Comment by erfgh 2 days ago
Comment by Betelbuddy 4 days ago
Comment by arunc 3 days ago
Comment by Aardappel 3 days ago
I guess people also differ by how much they are bothered by it :)
My other language, Lobster, has no semicolons at all :)
Comment by 0xjnml 21 hours ago
Comment by lemming 4 days ago
Comment by Aardappel 4 days ago
With Goose, the core design favors speed over everything else. Though not only was I able to make that safe, it is fairly pleasant to use. But it remains a low level systems language that requires you to think hard about data organization.
Lobster is a waaay more high level language made to be pleasant to use first, fast second. Surprisingly though, it can get pretty close in speed to C++/Rust nowadays too, but still a lot slower than Goose.
Comment by lemming 4 days ago
How have you found AI at writing Goose or Lobster code, if you give them a skill or something, are they relatively competent at actually writing code in the language?
Both are really interesting projects, BTW - thank you! I've been meaning to try Lobster out but haven't found time, I think this might be the push I needed.
Comment by Aardappel 4 days ago
Self-hosting would be cool too, but for both Lobster and Goose I've tried to keep it simple for people to build the language in any environment, which is why its still all in C++.
I don't use any "skills". From what I can see, the #1 way an AI produces "good code" is to simply work in the context of existing good code. I don't need to hold it by a style guide, it seems to infer that from context just fine. At least Fable does, other models less so.
Comment by andyferris 4 days ago
Comment by __mharrison__ 3 days ago
Comment by Aardappel 3 days ago
Even if you don't have such an example, pick a project that you think has "good code" (even if it is not your own), point the LLM at it, tell it to have a deep read of the code, and come up with a very in-depth coding guideline in a .md file with code patterns etc. Then put that .md in your new project and tell it to follow it.
Comment by vanderZwan 4 days ago
"Just Git Gud First" - Wouter van Oortmerssen
Comment by perrygeo 4 days ago
LLMs are pattern matching machines. Your code is the base template that will determine all patterns moving forward. No amount of context engineering or prompting can save your code from itself.
Pragmatically, it suggests we need a much greater investment in code quality, and much less hand-wringing over AI tooling.
Comment by vanderZwan 4 days ago
For context: I'm very active on the Goose discord (and have been following WvO's languages since Lobster was announced on Google Groups eons ago). I goof around there too, and forgot for a moment that outside of that chat it wouldn't be obvious that I'm being tongue-in-cheek.
Comment by osigurdson 4 days ago
Comment by malkia 4 days ago
Comment by jdw64 4 days ago
Comment by Aardappel 4 days ago
Comment by spacemarine1 4 days ago
Comment by jdw64 4 days ago
Comment by az09mugen 4 days ago
Comment by forgotpwd16 4 days ago
*And really in most if not all, Raku excluded**, languages.
**In Raku junctions can be specified with infix ops, i.e. a | b, a & b, a ^ b, equivalent to list ops any(...), all(...), one(...) respectively, and can define a custom one for none(...).
Comment by jibalt 4 days ago
Comment by stopping 4 days ago
Comment by jibalt 3 days ago
And FWIW, I actually think that "faster than C++ and than safe Rust" is clearer than the more idiomatic "faster than C++ or safe Rust", and certainly clearer than "faster than C++ and safe Rust", which looks like a conjunction of "C++" and "safe Rust". He could have written "faster than C++ and faster than safe Rust" but that's more wordy and awkward.
Enough of this pointless and irrelevant pedantics ... I won't respond further.
P.S. Just to be complete, here's an AI slop response:
You are completely right, and that is exactly why the author likely structured it that way.
In technical writing, "Faster than A and B" can be highly ambiguous. A reader could easily interpret it in two unintended ways:
• The Sum Interpretation: Faster than the speed of C++ and safe Rust combined (which makes no sense logically, but fits the literal grammar).
• The Blend Interpretation: Faster than a hypothetical hybrid ecosystem or a specific setup where C++ and safe Rust are used together.
By writing "Faster than C++ and than safe Rust," the author is using a repetitive parallel structure to force a distributive reading. It explicitly separates the two entities, making it clear that the language is:
1. Faster than C++
2. Faster than safe Rust
So while it sounds unnatural to a casual reader, it was a deliberate choice to ensure mathematical and logical precision over poetic style.
Comment by stopping 3 days ago
If a sentence has multiple "valid" interpretations, then it doesn't matter what the "correct" interpretation is. If someone says that a sentence is confusing or hard to read, you 100% must believe them and fix it. Dismissing concerns about clarity and ambiguity as merely "pedantic" is one reason why people fail to develop written communication skills. I have been burned many, many times in my career by making charitable assumptions about another engineer's ambiguous language, only to realize much later, after significant cost has been paid, that they had a completely different (and often wrong) idea.
Teaching people to be better writers is a hill I will gladly die on. I don't care if you defend your point or not, just read my comment and try to understand why someone would care deeply about this sort of thing.
Comment by az09mugen 4 days ago
Comment by cardboardguru 4 days ago
Comment by sockopen 3 days ago
Comment by vanderZwan 4 days ago
(And why isn't it Amiga E?)
Comment by Aardappel 4 days ago
As for Amiga E, I am very proud of having made it way back when obviously, but it doesn't stack up against my more modern languages (Goose and Lobster), so I think I'll leave it be :)
Comment by jghn 3 days ago
Comment by groundzeros2015 4 days ago
Comment by jcmoyer 4 days ago
    var words: u8[][>..] = [];
    for i in 5 { words.push(str("word", i)); }

    In C++ that is a vector<string>: one heap allocation for the vector,
    one per string, a pointer and a capacity per element, and a walk over
    all of them when it goes out of scope.
Comment by ModernMech 3 days ago
Comment by Someone 3 days ago
Comment by phoghed 3 days ago
Comment by tialaramex 3 days ago
Comment by glibg10b 3 days ago
Comment by tialaramex 3 days ago
Comment by saidnooneever 3 days ago
Comment by ModernMech 3 days ago
Comment by ShinyLeftPad 3 days ago
Comment by ModernMech 3 days ago
But what mistakes did the AI make about Goose? If it can say something wrong about a language it has much training data on, what's it saying wrong about a language with no training data at all? How can we trust anything it says about Goose?
Moreover, AI could have caught this mistake so even in using AI, it's clear AI wasn't used proficiently; it should have at least been tasked to proofread stuff like this.
Comment by dearing 3 days ago
The ol' saying garbage in, garbage out?
Comment by saidnooneever 3 days ago
Most things which are really close to perfect, have become so over time by feedback and amendments.
I think people who say this type of maybe dont read docs so often.. or only small parts of docs
Comment by vanderZwan 4 days ago
And these strings in Goose are 6 bytes, while the ones in C++ are apparently 16 to 24 bytes each.
Comment by tialaramex 3 days ago
Rust has had more interesting SSO types than C++ perhaps explicitly because it doesn't come with SSO out of the box although maybe also because C++ still isn't sure whether text is UTF-8 encoded even though it is 2026 now.
Comment by mossimage 3 days ago
Comment by felixguendling 3 days ago
Comment by mgaunard 3 days ago
The obvious downside is that resizing any string but the last requires moving everything down the stack.
With objects that never need resizing, you can of course have much simpler memory layouts.
Comment by malisper 4 days ago
For instance, how would you represent a hash table where the values are strings and at random, the program inserts or deletes a random string?
This doesn't seem like something you could easily represent. The only way I can think of is to keep a stack that holds all of your strings, and you periodically compact it.
Edit: Maybe you could also have a separate stack for strings of various sizes. One each for strings less than 8, 16, ... bytes. But at that point you're basically implementing your own malloc by hand.
Edit: Fwiw I do think Goose is very cool! I've had to hand-roll a lot of similar stuff in Rust before to speed up memory management
Comment by Aardappel 4 days ago
For example, you can build up a tree of all variable sized nodes inside a single array.
Where it gets interesting is if you must arbitrarily delete tree nodes, and you can't structure it to do that in stack order. The language has various tools for this, like fixed arrays with capacity, or pools of either single elements or runs of elements.
Comment by 112233 4 days ago
Comment by SkiFire13 3 days ago
In Rust parlance this would be the difference between a `Vec<Vec<T>>` (many `Vec`s, each can be resized) and a `Vec<Box<[T]>>` (many `Box`ed slices, each with a dynamic size, but none of them can be resized).
I bet you can exploit dynamically sized values to rebuild resizable values, with the downside however that you'll likely leak their memory until you exit the current scope.
Comment by progval 4 days ago
Comment by malisper 4 days ago
That example implements a linked list of integers. I'm curious how you would do a linked list of strings
Comment by progval 3 days ago
Comment by James_K 4 days ago
It's not entirely mad to do it this way, and I can see some benefits. For one, you might have multiple of these pools across the program for different data-types, which would make allocating to any one of them a cheaper operation. It is much more reference safe since you are only ever freeing stuff in a certain context and you can still never have dangling pointers. When you look at memory safe languages, they all default to this eventually. Like Rust in the advanced case will have you implementing your own allocator, lot's of games use this thing called ECS which is essentially a kind of allocator. Goose would just have it be more common.
Comment by malisper 4 days ago
Comment by andsoitis 4 days ago
Goose has a built-in generic hash table called dictionary<K, V>, provided by its standard library.
https://aardappel.github.io/goose/docs/stdlib.html#dictionar...
Comment by malisper 4 days ago
> Keys and values are fixed-size
so not quite what I'm looking for
Comment by andsoitis 4 days ago
Conceptually:
dictionary<i64, StringReference>
             |

             +----> "hello"

             +----> "a much longer string"

             +----> "x"
Comment by MeetingsBrowser 4 days ago
> Goose code holds typed references where the equivalent Rust holds u32 indices into an arena — and it is where a good share of the benchmark wins come from.
Comment by andsoitis 4 days ago
Comment by anigbrowl 4 days ago
I wonder if the name of the language was inspired by the way geese fly in formation, with trailing birds saving energy by flying inside the aerodynamic shadow of the leaders, and swapping in and out as needed. If so, a very nice metaphor for the memory management model.
I was also impressed by the documentation. As we know AI-generted docs tends to be rather mediocre, but the author has clearly invested time in making in readable such that the relevance and rationale of design decisions provide the context that a curious programmer needs to understand why things are implemented in a particular way.
I really appreciated the detailed samples, ranging from simple algorithmic theorems up to a small game. Again, I don't have the experience to rate the language vs others, but I was struck by readable the code was and how easy it was to follow task flow. Not having to think about classes is always a plus!
Anyway, I usually the the offering of a new language with dispassionate interest, as something to be aware of and but not get too invested in or familiar with until it gains enough popularity to have a good shot at longevity. Goose is the first language in a long time where I looked at it and immediately thought that I'd like to use it for its own sake.
Comment by Aardappel 4 days ago
The name is an animal because all my past PL designs are animals (I also made Lobster etc). Goose seemed like a fun name.
Comment by pradn 4 days ago
Still, for a large number of programs - like data-oriented applications - it’s probably a good fit. It might work ok with entity-component game systems as long as you reuse old memory…
Comment by Aardappel 4 days ago
If it is potentially completely unbounded, you need different solutions like a pool, or essentially reconstructing etc.
Comment by cornholio 3 days ago
Seems any compiled language with automatic memory can make use of the techniques to obtain speed ups.
Comment by pradn 3 days ago
Comment by ebiederm 4 days ago
From what little I read in the literature I seem to recall that there were enough programs with quite a bit more memory usage that they decided this approach was a dead end.
Does anyone know anymore details?
Comment by Aardappel 4 days ago
Back then though, they couldn't lean on large 64-bit address spaces like Goose can. They implemented all of this with a chain of blocks of memory instead, and tracked most of it at runtime that Goose now does at compile time.
https://github.com/aardappel/goose/blob/master/docs/design/p...
Comment by malkia 4 days ago
That reminds me of Dart Isolates - https://dart.dev/language/isolates
Comment by bobbydigitales 4 days ago
The relative references and built in binary structure validation also enable direct memory mapping of data structures and immediate use of network data. "Parsing" file and network data is often 100x slower than it needs to be." - John Carmack
Comment by pulse7 4 days ago
Comment by malisper 4 days ago
At compile time, Goose will analyze your program and determine a number of stacks, N, for it. N is the maximum number of "growable" items you can have in existence at any given point in time. Using virtual memory tricks, each stack can grow up to 2GB, but it uses a contiguous address space and only uses as much physical memory as it actually needs.
For the program you're describing, I think you would end up with two stacks: one to parse the input and a second to print it. When you parse the input, Goose reads characters from the string one at a time and puts them onto the stack. Once it has hit the end of value, it will update the stack so it now represents the decoded JSON value (strings will just leave the characters in place, numbers will pop off the characters and push the number onto the stack). Goose repeats this until it has parsed the whole JSON, and now the whole JSON is on the stack.
Then, when you print the JSON, Goose uses the second stack to build a string. Like the parsing approach, it iterates through each element of the JSON and pushes its string representation onto the stack. Once it's done, it resets the stack pointers to free the memory.
This is really nice because allocating memory is just adding to the pointer, and freeing it is subtracting from the pointer.
In contrast, Rust automatically inserts malloc() and free() calls throughout your code, which are much more expensive than pointer arithmetic. On top of that, freeing a vector of heap-allocated objects is O(n), whereas if done right in Goose, it would be O(1)
Comment by Aardappel 4 days ago
Goose can store entire trees (of variable sized things) inside an array.
Comment by stickfigure 4 days ago
Apache modules worked like this (still do, presumably). Each request has a stack; allocations bump the stack pointer; when a request is finished, the stack pointer is reset. Incredibly efficient as long as you don't need to keep memory longer than a single request.
Looks like in Goose, each scope acts like an apache "request".
Comment by abcd_f 4 days ago
Comment by Xirdus 4 days ago
Comment by stickfigure 4 days ago
Comment by andsoitis 4 days ago
Check the features section (https://aardappel.github.io/goose/#features), which starts off with how memory works.
Comment by Aardappel 4 days ago
Comment by pixelesque 4 days ago
e.g. I see a general lack of reserve()s on strings and vectors (a few tests do use them a bit, like `graph` and `particles`), and there are several other things which I wouldn't personally call "optimized", so I assume those ones are the 'idiomatic' ones?
Same goes for the Rust code: a lot of the code seems to be using Vec::new() and String::new(), instead of ::with_capacity() which would optimize the memory re-allocation (reducing it as the containers/strings grow).
Comment by dash2 4 days ago
Comment by Aardappel 4 days ago
I preferred people being able to play with it rather than worrying about any claude-isms :)
Comment by dash2 3 days ago
Comment by jnpnj 4 days ago
ps: Ah well, I could have searched before asking https://strlen.com/programming-languages/
super neat history !
Comment by Aardappel 4 days ago
Comment by onlyrealcuzzo 4 days ago
Something that I'm interested in: How fast is the compilation speed on large programs compared to Zig, C, Go?
My ideal language is safer than Rust (no deadlocks / livelocks, no stack overflow from recursion), is optimized for cache locality, but compiles faster than Zig.
This seems like it's close to 2/3.
Comment by Aardappel 4 days ago
That said, during development/iteration/testing, you can just the built-in JIT, which is based on libtcc (which is very fast), as don't as you don't mind a ~3x runtime slowdown.
Comment by briandw 4 days ago
Comment by loufe 4 days ago
Comment by jkl5xx 3 days ago
Comment by jeff_ciesielski 3 days ago
Ported a couple of algorithms from my quite large commercial rust codebase and they were significantly faster in goose. Was wow'd, but the big gain was actually that goose just led the LLM to use more efficient (though admittedly slightly less rust-ideomatic but still safe) data structures, so porting them back kept nearly all of the gain (and in one case, even more).
The obvious 'no shit' comment is 'well your code just wasn't optimized', which is partially true, there was obviously a fair bit left on the table. What I find more interesting is that for darn near zero cost, having an an LLM explore in different languages led to a better outcome than me sitting here running perf and squeezing for cycles.
I'm sure that as I build up a cookbook for my codebase this will be less useful over time, but for now, this is going to be how I approach first order performance optimization.
Nice work, cool tool, plz de-ai the docs :D
Comment by weinzierl 4 days ago
Where does Goose sit when classified along these dimensions?
Sure, performance is right there on the packaging but no word about UB in the README. I read "Goose has syntax familiar to C and Rust" as DX in the same ballpark, but is it a performance first or safety first language.
If it is the former it occupies the same crowded niche as C++ and its many cousins and will have a hard time.
If it's the latter it will have much more room to prosper. We don't have enough languages in the niche that Rust and Ada fill right now.
Comment by Aardappel 4 days ago
It is obviously has a lot of potential to be very fast.
It even does pretty good on DX. There is no borrow checker to fight. Algorithms that need indices in Rust are strongly typed references in Goose. Generally pleasant easy to read and write code.
The biggest thing against DX may be exactly where performance comes from: you need to think a bit on where to store your data :)
Comment by groundzeros2015 4 days ago
Where is the behavior specified?
Comment by Aardappel 4 days ago
Comment by groundzeros2015 4 days ago
Comment by vanderZwan 4 days ago
> Goose: my latest programming language. Safer, faster and less memory than Rust/C++ for algorithms where tightly packed, flat data structures matter.
> It can represent more kinds of data structures as flat, pointer-free bytes than any language I know.
https://xitter.cf/wvo/status/2107979660558766351
So one way to answer might be: how often do you reach for unsafe when using Rust? If you don't I guess Rust is safer. If you do… it gets trickier.
As for UB, I guess you could try looking through the spec and/or the reference? Like, the code is mostly generated by Claude after WvO wrote a specification. If it were anyone else I'd be worried, but given WvO's cv I actually suspect that means the spec leaves basically no ambiguity.
However, Goose compiles to C. Does that by definition mean UB sneaks in, or is there a "UB free" C subset? I don't write C, so I don't really know.
Comment by jibalt 4 days ago
UB in C potentially destroys the universe so C programmers do their best to avoid it. A backend that generates C code is a lot more easily constrained than arbitrary manual code. While it's conceivable that a C backend could produce UB code, it would be a severe bug and isn't likely. It most certainly isn't "by definition" ... that suggests some serious conceptual error.
Comment by weinzierl 4 days ago
The complete omission of UB in the README could be one of two things. Either that the topic is not important or that it is considered a given and not worth mentioning.
Comment by vanderZwan 4 days ago
Note also the fact that e.g. array indexing has bounds checks without escape hatches for the programmer, but the compiler can elide quite a few of them, and the language has tools to help the programmer write code that is guaranteed to be check-free.
I think that suggests the ambition is to compete with Rust in the domain of combining safety with not compromising on performance.
Comment by jibalt 4 days ago
Comment by adastra22 4 days ago
Comment by AnEro 4 days ago
Comment by kadw 4 days ago
Embassy (https://github.com/embassy-rs/embassy) uses this concept of no heap allocation and I find it really solid. Even if you write in C, most of the times you don't use heap. MISRA, the C coding standard for automotives, doesn't allow dynamic allocation!
Comment by Aardappel 4 days ago
Comment by malkia 4 days ago
But sounds great for 64-bit user space, with enough (48-bit, or more) virtual addressing available. Obviously one can hit some snags if for some reason quite large allocations has to be done, but maybe one has to rethink that too.
I'm starting to fall in love with this approach ;)
Comment by exaroth 3 days ago
Comment by amai 4 days ago
This was my first programming language. Good old times!
Comment by Aardappel 3 days ago
Comment by andsoitis 4 days ago
Comment by vanderZwan 4 days ago
Comment by onlyrealcuzzo 4 days ago
Comment by nvarsj 4 days ago
Comment by malkia 4 days ago
If the host needs to load several of these .wasm, compiled with goose, then it'll have to run them in separate (browser) instances too (or maybe that's how wasm works by default - not sure).
It just got me thinking - the languge is prepared to translate into javascript workers, because it's really single threaded by nature with communication between threads (or put in the dart languages term "isolates"), which makes them perfect for the browser, now the only question is the memory layout.
Comment by Aardappel 4 days ago
Comment by creata 4 days ago
Comment by Aardappel 4 days ago
Comment by calvinmorrison 4 days ago
Comment by Aardappel 4 days ago
In Goose, things grow in-place only, since they have a large amount of address space reserved.
Comment by calvinmorrison 4 days ago
Comment by hbogert 3 days ago
Comment by malkia 4 days ago
I guess there would be some penalty to be paid here for smaller pages, but being mostly contigous might also help some.
That to be said, such language seems to require 64-bit virtual address space in order to function reasonably, right?
Also a .dll written in it might not be the best suited, for example if loaded in the middle of fragmented virtual address space it may need to find itself hard to allocate N contigious data stacks (do they absolutely have to be contiguous, what if they are simply ropes or deques or connected chunks ... obviously if some data structure requires to be contigous that would be a problem, but maybe this can be expressed somehow.... or maybe I'm overthinking here).
Super excited about this!
Comment by Aardappel 4 days ago
Comment by wewewedxfgdf 4 days ago
Comment by Aardappel 4 days ago
Comment by wewewedxfgdf 4 days ago
Selling the positives for a new programming languages should go hand in hand with a realistic thorough analysis of the negatives.
Negatives of the language as a brief point 18 on the tutorial makes the negatives look hidden.
Comment by malkia 4 days ago
Comment by wewewedxfgdf 4 days ago
But, as all good salespeople do, they focus on the positive and leave the negative in the fine print.
Selling happens everywhere all the time without price.
Comment by spopejoy 4 days ago
As in nothing functional at all? Or are there anonymous functions etc?
Comment by Aardappel 3 days ago
Comment by hackrmn 4 days ago
Comment by saidnooneever 3 days ago
Either way nice to see more options in this space.
Do you know a bit of an ETA / roadmap for certain features like the dynamically sized moves and struct members?
p.s. love potato and geese so feelin kinda biassed towards being excited about this :D
Comment by Aardappel 3 days ago
You'll have to explain what you mean exactly by "dynamically sized moves and struct members".
Comment by baud9600 4 days ago
I’d love to see 1st class lightweight ‘processes’ and typed comms, like CSP. These light processes would be cheap to spawn in the thousands, with synchronous comms. So it’s possible to quickly use arbitrary networks rather than OS thread worker pools with queues. Maybe like:
fn produce(out: chan<i32>) { for i in 1000 { send(out, i); } }
fn consume(inp: chan<i32>) { for i in 1000 { print(recv(inp)); } }
fn main() { let c = chan<i32>();
  par {
    produce(c);
    consume(c);
  }
}
Comment by Aardappel 4 days ago
Comment by rfgplk 4 days ago
If anyone is interested, I'm fairly close to finalizing Slang and I'm considering open-sourcing it in the near future. What originally started as a simple register based lang for an embeddable VM turned into an insanely expressive meta?programming language. Full system Fω, expansive whole program reflection (you can reflect on absolutely anything), string memory & logic safety..
You can do stuff like this:
   (fn answer () -> i64 0)
   (defpass build-answer
     (phase source)
     (transform (lambda (f)
       (fn-with f 'body '(let ((a (arr (42)))) (at a 0)))))
     (safety (lambda (goal) (syntax (refl)))))
   (run-pass build-answer answer)
   (fnmut answer
     (transform (lambda (f)
       (if (memory-safe? (check-memory (current-program)))
         f (syntax-error 'unproved-memory)))))
   (defpass inspect-ssa
     (phase ssa)
     (transform (lambda (f)
       (if (memory-safe? (check-memory (ssa-current-program)))
         f (syntax-error 'unproved-ssa-memory))))
     (proof (lambda (goal) (syntax (refl)))))
   (run-pass inspect-ssa answer)
   (answer)
   (fn next ((i i64)) -> i64 (+ i 1))
   (fncontract next
     (ensures result (successor (Eq i64 result (+ (old i) 1)) auto)))
   (fn read-second ((i i64)) -> i64
     (let ((a (arr (0 42)))) (at a i)))
   (fncontract read-second (requires (one (Eq i64 i 1))))
   (let ((i (next 0)))
     (with-proof ((one (Eq i64 i 1) (result-proof i successor)))
       (print (read-second i))))
   (var answer 0)
   (asm (input rdi 20)
        (input rsi 22)
        (output rax answer)
        (mov rdi rax)
        (add rsi rax))
   (print answer)

   (macroop \ (a) (asm (mov a rax)))
   (\ 42)

   (print (llvm add 20 22))
   (print (->i64 (llvm fused-multiply-add (f64) 6.0 7.0 0.0)))
   (llvm fn sum32 ((x i32) (y i32)) -> i32
     (block entry
       (value answer (llvm add x y (declare (flags nsw))))
       (llvm return answer)))
   (print (->i64 (sum32 (the i32 20) (the i32 22))))
Comment by gspr 4 days ago
So now your safety and performance issues are in the LLM and whatever prose you feed it for it to generate slang. Have you gained anything?
(Not meant to detract from the language. It's just that this particular goal seems... strange).
Comment by ModernMech 4 days ago
Comment by anthk 4 days ago
Comment by IshKebab 4 days ago
Comment by ivanjermakov 4 days ago
Comment by hbogert 3 days ago
Comment by IshKebab 3 days ago
To a large degree, yes. But I would say it's more like "lack of care, bad project".
Comment by MisterTea 2 days ago
This is what Ada does, at least the GNAT implementation.
Comment by twiss 4 days ago
Does this mean you have to know the name of the function calling you that's supposed to handle the error? What if you're a library and don't know that?
Comment by vanderZwan 3 days ago
One idea that came up was this: you could define a particuda function name as the "landing pad" for handling particular error kinds. Then you "wrap" calls to the library in a function with this name. Here's a part from a larger worked example:
    fn catch_io<F: fn()>() -> IoError {
      F();
      return IoError{ message: "", ok: true }
    }

    let err = catch_io() { c(); };
Mind you, this was just discussion, no experience with how well this would work in practice.
Comment by twiss 3 days ago
Even better, you could give it some syntactic sugar like `throw IoError{}`? ;)
P.S. I think the `IoError { message, ok }` type is suspiciously close to `Result<(), String>`.. And if you want to return a value in the success case too it'll become even closer. Perhaps it's best to lean into that and find the calling function that can return an IoError as one of the possible values?
Comment by daoxid 4 days ago
Comment by malisper 4 days ago
Rust does a similar thing. When a function returns a value, a location for it will be put in the callers stack frame. That means it automatically stack-allocates values when feasible. The downside in Rust is you need to know the size of the value at compile time whereas Goose can do it for arbitrarily sized values
Comment by sergiotapia 3 days ago
Comment by alfiedotwtf 4 days ago
Comment by swiftcoder 4 days ago
Comment by rvz 4 days ago
Yet, the author expects YOU to read all of what they didn't write. So I ain't reading all of that.
Comment by tonis2 3 days ago
Comment by nlitened 3 days ago
Comment by rrook 3 days ago
Comment by gigatexal 4 days ago
Comment by pron 4 days ago
Comment by Aardappel 4 days ago
Comment by pron 4 days ago
Comment by Aardappel 4 days ago
Goose's thread system however has typed queue's inspired by the Linda Coordination Language https://en.wikipedia.org/wiki/Linda_(coordination_language) that can most definitely model some interesting data structures.
Comment by whacko_quacko 4 days ago
Comment by avadodin 3 days ago
Comment by cartothug 4 days ago
Comment by RetardedBastard 4 days ago
Comment by cartothug 4 days ago
Comment by ModernMech 4 days ago
Comment by salah7252 4 days ago
Comment by cardanome 4 days ago
There might be some decent design ideas there but if you can't be arsed to write them down in your own words but instead make me read AI generated slop I am out.
Comment by Panzerschrek 4 days ago
Comment by cardanome 3 days ago
Mandatory initialization, strong typing, context free grammar, lots of good basics. If you get the C++ header converter to work so you can use most C++ libraries I could see this as a great C++ replacement.
Comment by stellalo 4 days ago
Edit: I guess one would still miss Goose’s memory layout, which is (if I understand correctly) where it wins in performance.
Comment by FrustratedMonky 4 days ago
Edit Man, two posting about Goose back to back. Carmack alone might be enough to read further.
Comment by tobiolo 4 days ago
Comment by hbogert 4 days ago
Comment by Aardappel 3 days ago
Comment by timcobb 4 days ago
What are the ergonomics of this I wonder.
Comment by vanderZwan 4 days ago
Comment by Panzerschrek 4 days ago
I doubt this can work well in all cases. Sooner or later one needs proper heap.
Comment by skrebbel 4 days ago
Comment by wegwerper 4 days ago
I find it hard to invest any time in learning about a project if the surface symbols indicate it being a low effort project.
Comment by forgotpwd16 4 days ago
Comment by amenhotep 3 days ago
Comment by groundzeros2015 4 days ago
Comment by Aardappel 4 days ago
Comment by groundzeros2015 4 days ago
Comment by salah7252 4 days ago
Comment by FrankWilhoit 4 days ago
Comment by baalimago 4 days ago
Comment by asinglesprinkle 4 days ago
Comment by lisp2240 4 days ago
https://www.motherjones.com/politics/2026/10/palmer-luckey-a...
Can't wait find out what terrible crimes against humanity Goose will cause.
Comment by nnevatie 4 days ago
And doc is the slop.
Comment by shooshx 4 days ago
Comment by iacuobos 4 days ago
Comment by andsoitis 4 days ago
Why Goose - https://aardappel.github.io/goose/#why-goose
Comment by anonymous908213 4 days ago
Comment by zeng_che 4 days ago
Comment by ethanhood_okroh 4 days ago
Comment by mi_lk 4 days ago
Comment by stefanos82 4 days ago
Comment by frangonf 4 days ago
Comment by andsoitis 4 days ago
I could follow the link and read the thread and I don't have an X account.
You can also check out the language's website by googling "goose programming language", which should lead you to: https://aardappel.github.io/goose/index.html
Comment by celsoazevedo 4 days ago
What X shows me: https://celsoazevedo.com/files/2026/x.webp
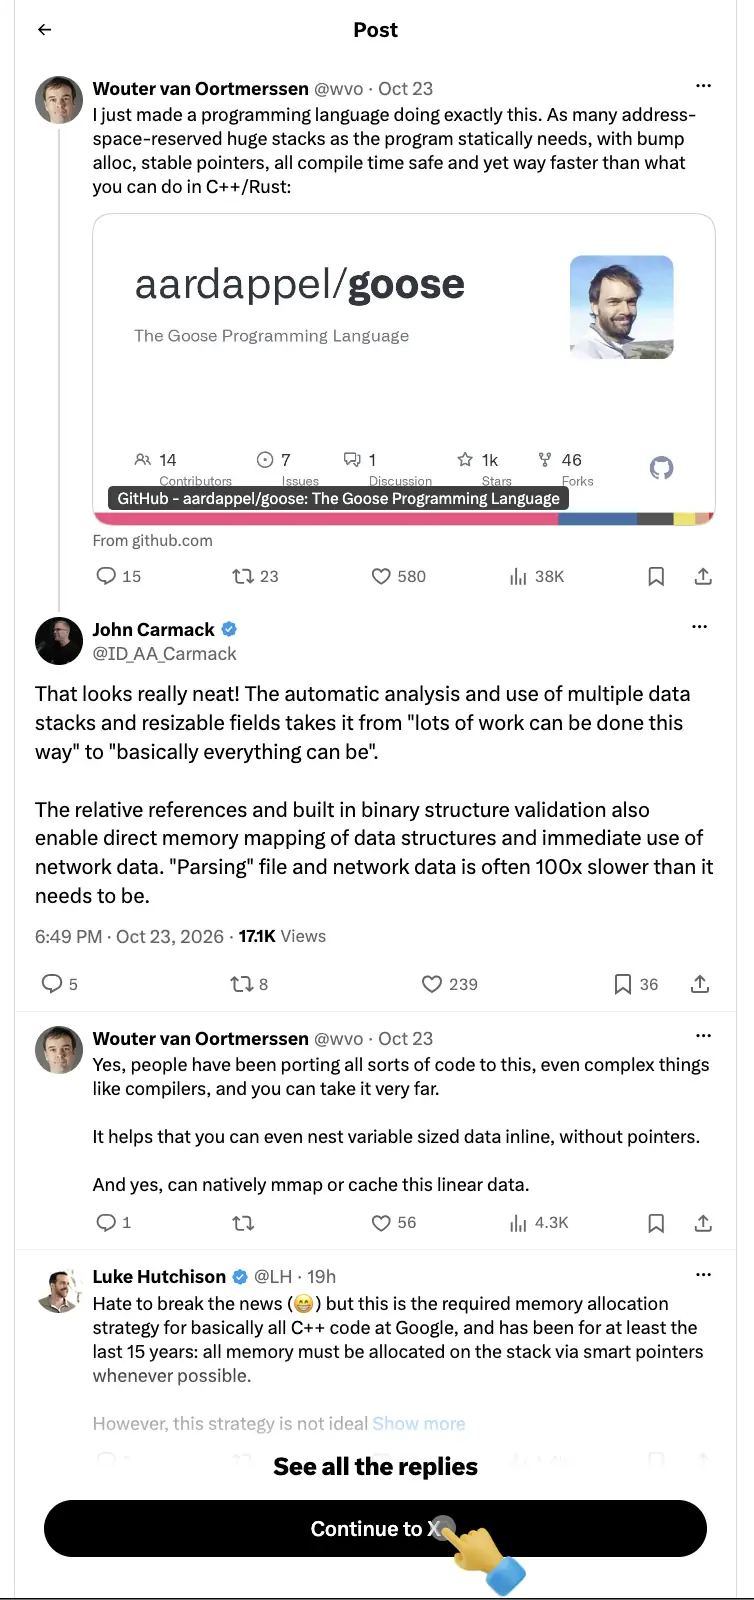
With a login/nitter: https://celsoazevedo.com/files/2026/nitter.webp
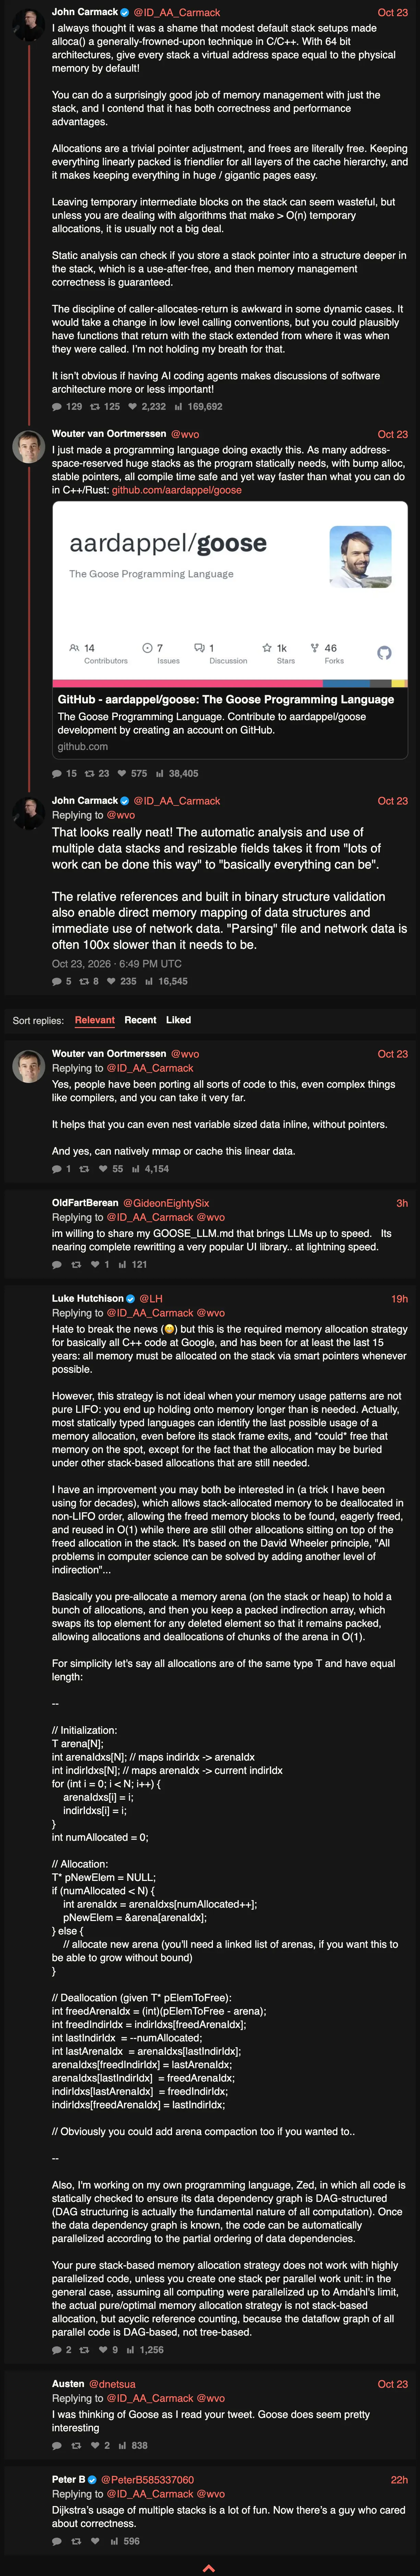
Comment by cosmotic 4 days ago
Comment by mcdonje 4 days ago
Comment by mi_lk 4 days ago
Comment by randyrand 4 days ago
Comment by DoesntMatter22 4 days ago
Comment by genxy 4 days ago
Comment by joshsyn 4 days ago
Comment by agentic-affairs 4 days ago
Comment by spying_lg_tv 4 days ago
Comment by mihaaly 4 days ago
Comment by geoffbp 4 days ago